Here's a screenshot from my locally hosted emotive audiobook narration software backed by Qwen3.6 for checking grammar (and invoking a custom SymSpell implementation for spelling):
Nonetheless, Dr. Carvalho agrees with avoiding sugary drinks:
"We have a lot of recent evidence, recent studies after [Lustig's] talk. The link between soda and weight gain and obesity and other chronic diseases is quite strong."
Drink fewer sugary beverages, consume fewer calories (eat less), exercise, and drink less alcohol.
KeenLore is my emotive audiobook creator, which I've been working on for the past several months to help me narrate my sci-fi novel. Here's a slightly outdated demo video:
I've since added character ages (child to supercentenarian voices, consistent relative to their base adult voice), crowd chants (2 to 100 people works flawlessly), case sensitivity for character aliases (to help detect quotation attributions), custom phonetics, and English speaking characters can have a variety of accents applied. Will soon have Chatterbox driving the novel's narration. Screenshot:
Another HN user suggested embedding sound effects. The lead author of MOSS-TTS emailed me that the next version will have a SOTA voice designer. Poke around the voice design space, you'll find text-to-effects here and there. I certainly have my eyes on this space.
Laws will seldom work 100% of the time, but I profoundly disagree with your implied attitude. "They don't cover this future case, so we shouldn't do anything now".
People will take to wearing corrective contact lenses that will have recording capabilities in a few years. This is going to open up a huge can of worms for privacy, cinemas, and more. I did not write that we mustn't do anything about it right now, only that it is short-sighted. Creating laws about wearable recording devices would benefit from addressing near-future technology, which will include easily concealed digitally augmented corrective lenses.
I'm looking to put together a tutorial discussing fundamentals of Blues and Swing partner dancing. I have the raw source material. I'd like to change the background, change the attire of instructors (myself and a friend), and fix up other issues (dead space, umms, and other gaffs). The footage is about 22 minutes, and can be split into 5 different segments of about 3 - 4 minutes each.
I'm running Arch Linux and would rather not install DaVinci Resolve, but Blender would be fine for the non-linear video editor.
My plan is to use ChatCut to trim and split into the different sections. After I have the five segments, what would you suggest for swapping the background (environment) and attire? There are two simultaneous camera shots (front and side) that I'd like to stitch together as well.
Any suggestions? (Paying someone a couple of hundred $CAD to take this task off my plate would also work.)
No cloud, no tokens to pay. Reads a book using a full cast of characters. Quotation attribution detection (for my novel) is at 97.2% accuracy (485/499 quotes identified and assigned correctly). The autofill of character voice descriptions uses the prose to determine how the character sounds.
Employs Gemma 4[1] for the prose analysis (voice fills, quotation detection) and Qwen3 TTS Voice Design[2] for creating voice samples. Runs on an 8GB NVIDIA T1000 GPU card, 96 GB RAM, and a AMD Ryzen 5 7600.
I've been working on a similar project all year and as a tip, you should try Fish Audio or Higgs as a replacement for Qwen3. Both yield much better prosody and are much easier to listen to for long runs.
I wasn't able to find a version of these that can create voice samples based on voice designs. Do you mean to use Qwen3 TTS Voice Design to create samples followed by Higgs or Fish Audio to clone the sample voices and narrate the novel?
MOSS-TTS 2.0 will apparently have voice design, as well, on par with ElevenLabs quality.
For the voice design, these don’t support it, but for the final render, they’re much better. So your pipeline could for example generate voices with one tool and render with another.
It's cool technology and I read a lot of audiobooks, even hundreds of hours of TTS. I feel like my brain can fill in the character voices from the text - on the page it's not like they're different fonts.
I understand audiobook narrators often do it, and that's fun. But it's not so critical in my opinion
> annotate your text with extra 'stage directions'
Good idea, not something I've considered yet. Wouldn't take much to add it since there's already a feature for selecting a quotation and assigning it an intonation. Same infrastructure could be reused to select arbitrary text and assign stage directions.
Nice! One suggestion: don't just make this apply to text, but also to a specific cursor position (you could say a zero-length text selection where start=end). That's natural if you eg want to say that between one sentence and the next, or one word and the next, you want to insert the sound of a train arriving or a sigh.


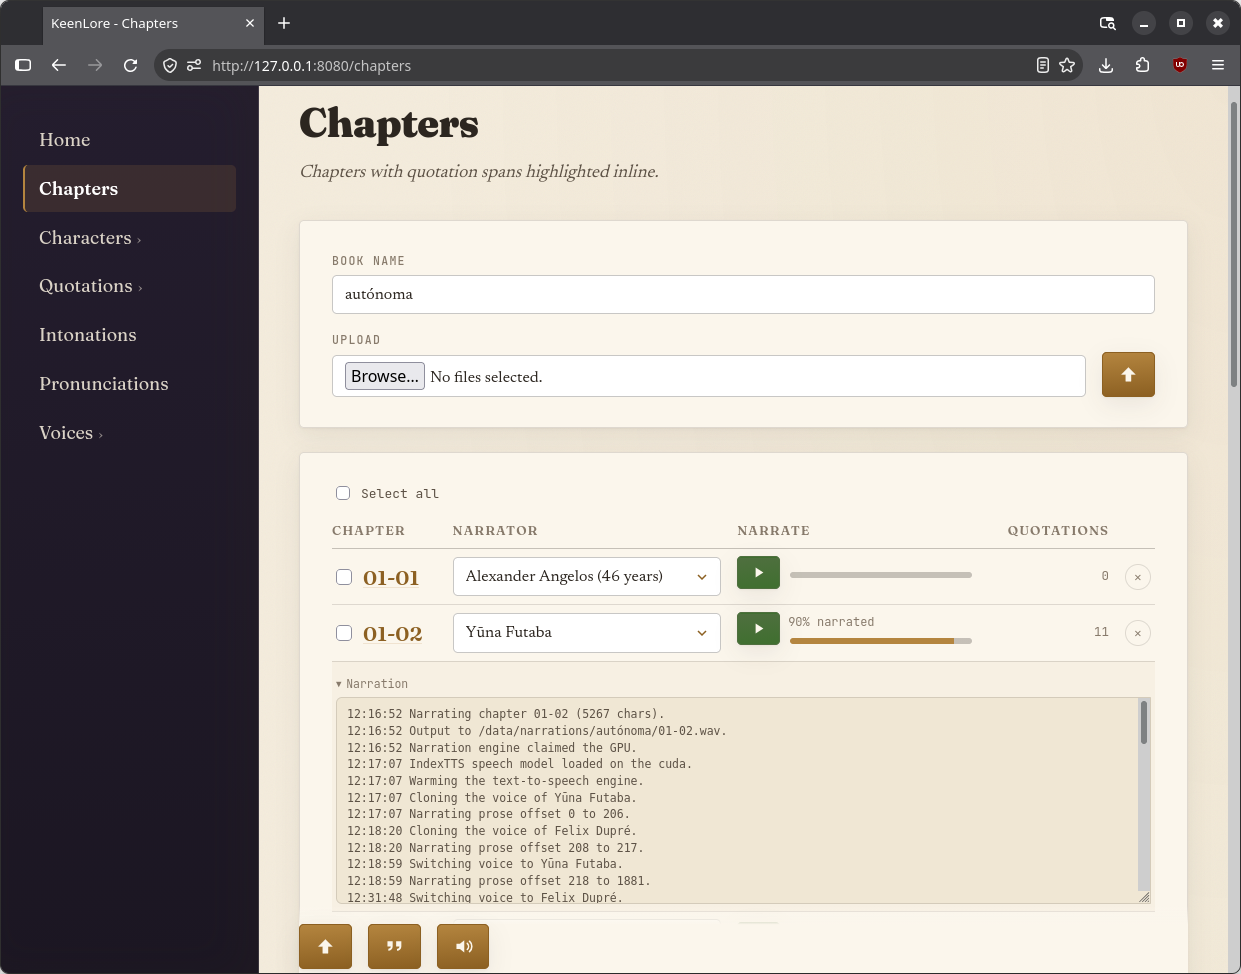
https://i.ibb.co/2LLVZ0N/keenlore-proofread.png
It took about two hours to code using Opus 5.5. Finding and fixing grammar mistakes is quick. Not sure why magazines aren't doing similar checks.
reply