The article doesn't really make it clear how much of an effect this has
> People younger than 60 who drank one to four cups of coffee, particularly filtered coffee, had lower rates of artery disease and death
> The study is observational and doesn't prove that filtered coffee is healthier than unfiltered coffee
> a cup of unfiltered coffee contains 30 times more diterpenes than a cup of filtered coffee
This sentence in particular is kinda meaningless without specifying the specific amounts and what they mean. For instance, saying "an unfiltered cup of coffee contains 30 times more salt than a filtered cup" would not mean much if one contains 1 ug and the other 30ug, but would be very significant if it was e.g. 1 vs 30g
The idea is that optional values are either some value or no value, but sometimes the inner "some value" bit can itself be an optional value (in Rust this would be Option>, in C++ it'd be std::optional>, in Python it'd hypothetically be Option[Option[T]], etc.). Such a situation gives you three possible states:
- You have an inner value and the inner value is something non-null (an integer, a string, another optional, etc.)
- You have an inner value and the inner value is null
- You do not have an inner value
The problem, from what I understand, is that Option[T] in Python is equivalent to the union type T | None, and union types are flattened (e.g., (T | U) | V is equivalent to T | U | V) and duplicates are ignored (e.g., T | U | T is equivalent to T | U). As a result, Option[Option[T]] is equivalent to (T | None) | None, which is equivalent to T | None | None, which is finally equivalent to T | None, which means you lose the distinction between "No inner value" and "Inner value is present but is None".
As a more concrete (albeit somewhat contrived) example, say there's some API you can query for the owner of a particular document ID where the document ID may or may not refer to an actual document (e.g., maybe you got it from a cache and the document has since been deleted). One way to express this would be (using Rust syntax)
fn get_owner(id: DocumentId) -> Option> { ... }
So if you get None, the document does not exist; if you get Some(None), the document exists but it has no owner; and if you get Some() the document exists and it has an owner.
(This can probably be done better by creating new enums, but it's an example so give me a bit of slack)
So now you're in the pickle the OP describes: you can end up with a None, but you no longer knonw whether it means "no document" or "no owner". The Python solution is to basically create a different name for either the outer None (e.g., MISSING as in the OP) or the inner one (e.g., NO_OWNER or the like).
Most languages can do this if it's what you want. In Python it would be:
    class Some[T]:
        value: T

    type Option[T] = Some[T] | None

    def get_owner(id: DocumentId) -> Option[Option[UserId]]: ...

    match get_owner(document_id):
        case None:
            ...
        case Some(None):
            ...
        case Some(Some(x)):
            ...
Yeah, that's more like what you would do if you wanted to translate the entire concept to Python instead of just the signature, and I probably should have mentioned that alternative as well (or should have said "A Python solution"). Can't say I've seen this approach used in practice, interestingly, though I'm probably not nearly as familiar with the Python that exists out there as most other commenters here.
The name clash is unfortunate, but luckily naming things is famously one of the easiest problems in CS so that should be trivial to solve :P
I see, thanks. Though this feels like something that would always have a better alternative than returning Some(None). Probably a new enum, or in Python's case, exceptions (e.g. instead of returning a value if the document is missing, you'd raise DocumentMissingError or something)
This seems really silly to me. Why does get_owner need to differentiate between the document exists and maybe has an owner or the document doesn’t exist and thus has no owner. In both cases getting no owner should suffice? Why are you using get_owner to try and figure out if the document exists? Can you give an example where this distinction actually matters?
You run into this issue any time you do a LEFT JOIN in sql and the field you care about is nullable.
The right side value could be null because it was missing, or because it was literally null. You resolve by checking the join key, and if that is itself nullable, you’re forced to introduce a sentinel
Depends on what exactly you plan on doing with the information, I'd imagine. I don't think it's necessarily a given that "no document" and "no owner" should be handled identically (e.g., searching for the updated document to try again vs. returning an operation-not-allowed error).
> Why are you using get_owner to try and figure out if the document exists?
Potential TOCTOU issues, perhaps? As I mentioned the document could have vanished out from under you so detecting this situation could let handle things appropriately (though to be fair that argument could probably extend to future operations as well).
Maybe a versioned filesystem would have made a bit more sense, where None would indicate a new version is available? Another example I've seen mentioned is trying to get a key-value pair from a JSON where the key may be missing.
But in any case, I did say it was a bit of a contrived example, so cut me a bit of slack :P It was just the first thing that came to mind.
The examples sibling comments give are probably more practical.
> I don't think it's necessarily a given that "no document" and "no owner" should be handled identically (e.g., searching for the updated document to try again vs. returning an operation-not-allowed error).
If you care whether a document exists or not, you should use an API that exclusively tells you that instead of expecting everything related to documents telling you if the document exists or not. Otherwise you’re overloading the meaning. A non existent document has no owner. An API to fetch the owner of the document should not care if it exists or not, it does not matter.
As I said, that sounds like a recipe for potential TOCTOU errors.
But again, this was an off-the-cuff example that I explicitly described as contrived from the start. I could probably flesh it out to make more sense, but I think it'd be easier just to refer to sibling comments rather than bikeshed this to death.
Not really? It returns no owner if the document is deleted or just does not exist, which is accurate. Why do you need get_owner to tell you if the document exists or not? If anything it should be an error if the document doesn’t exist because you’ve violated a precondition.
> It returns no owner if the document is deleted or just does not exist, which is accurate.
"I don't know" is not the same as "definitely no owner". You may handle the two answers the same for a particular scenario, but then again you may not.
Again, consider the case where get_owner is working on some kind of cache (in which case sure, the function name could stand to be improved). If the document is no longer in the cache it could be because it was actually deleted or because it was simply evicted to make room for other entries. In general you cannot assume that a missing cache entry is equivalent to the document existing and having no owner.
Or similarly (and also yet again), consider the case where get_owner is working on a versioned filesystem, in which case the outer optional could indicate that the (generational) document ID is out of date. In such a case treating "I don't know" and "no owner" the same is incorrect because the owner could have been updated from "no owner" to something else (such a case would likely be more realistically handled by returning a Result, SomeErrorKind>, though, given the myriad other ways a file system handle can go stale)
> Why do you need get_owner to tell you if the document exists or not?
Because sometimes there is no good alternative. Asking a cache whether it has an entry and then trying to get the entry value in a separate operation (particularly in a concurrent environment) is a classic setup for TOCTOU errors. You can say something similar for the versioned file system example.
> If anything it should be an error if the document doesn’t exist because you’ve violated a precondition.
I mean, enabling that kind of handling is precisely the point of the outer optional?
Maybe a different example works better for your mental model:
A user can set custom settings, and those settings may or may not have a value assigned to them. For example, one setting is optimization level, another option is a debug flag.
You want to have a unified interface to get information about settings, queried through some intermediate system. (lets just say it is limited to querying specific settings, rather than getting the entire list, due to legacy constraints in this case) Because for some settings you just care about them existing and for others you care about the actual value, you have to differentiate between a setting that contains something, a setting that contains nothing, and one that doesnt exist.
The answer is they don't in practical code but they come up in generic code, where you want to wrap something that is already returning an optional in your optional. In languages that do support optional[optional[whatever]], if you every actually write that you know you've messed up your API.
They absolutely do in practical non-generic code. A case I personally encounter regularly is json APIs which distinguish between a key being missing and one being set to null in a structure.
If you have a map, get(key) returns Option[ValueT]: None if the key is missing, Some(value) otherwise. If the value type itself is, say, Optional[String], your return type is Optional[Optional[String]]. Here None still always means the key is missing, while Some(None) means the value is just None.
If I understand the article correctly, there is no boiling water, it uses hot air only. It says the concentrated solar generates air up to nearly 1000 degrees, and that's used to heat up compressed air to run through a turbine, with the eziting air at around 250 degrees. Burning fuel would replace the initial source of hot air. Burning fossil fuels to get hot air and then dumping 250 degree air to the environment doesn't seem very efficient, but the article doesn't mention anything about the efficiency of the process with either source.
Does say the hot air at the end can be used for industrial processes, so it might not be completely lost
The 1000 degree air is not used directly to drive turbines, but instead to deliver heat to a heat storage unit via a heat exchanger. The solar-heated air, after flowing through the heat exchanger, is still around 250 degrees and the article mentions some possible uses of that heated air (again, not generation).
Generation occurs using heat coming from the heat storage unit, not using the solar-heated hot air. Since the heat storage unit can also be fed by hot air heated via other means, this makes the heat storage unit "source neutral" - it can be heated by solar or fossil fuel combustion (or whatever).
The turbines are "downstream" of the heat storage unit.
GTA games are, as far as I know, mostly built by Rockstar North studio (formerly DMA Design), which is located in Scotland. Obbe Vermeij, former Rockstar North employee, has written some interesting blog posts about the development of GTA from 3 through San Andreas, which can be found archived here: https://gist.github.com/WillPresley/d57d48b3d5f7f7b4bde4a2a3... (he has taken the blog down). It seems that, at least in that era, Rockstar New York was mostly handling the story and voice acting.
Geothermal is not nuclear fission. It's some combination of primordial heat from the formation of the Earth (which was gravitational energy) and radioactive decay (which is distinct from fission).
> Seems like a git push credential of some kind was compromised, not an npm or GitHub token. Still working with the GitHub team to get some better forensics on what/how. The attack consisted of malicious commits and tagged pushes to main.
So it didn't go through review, it was pushed straight to main. It also seems their publishing pipeline was already secured against this sort of thing:
> Zod's release flow was already secured against kind of attack via trusted publishing and a dedicated GitHub environment for secure deployments. Zod's release CI worked as designed and was already secure against this; NPM's malware scanning didn't prevent any malicious here.
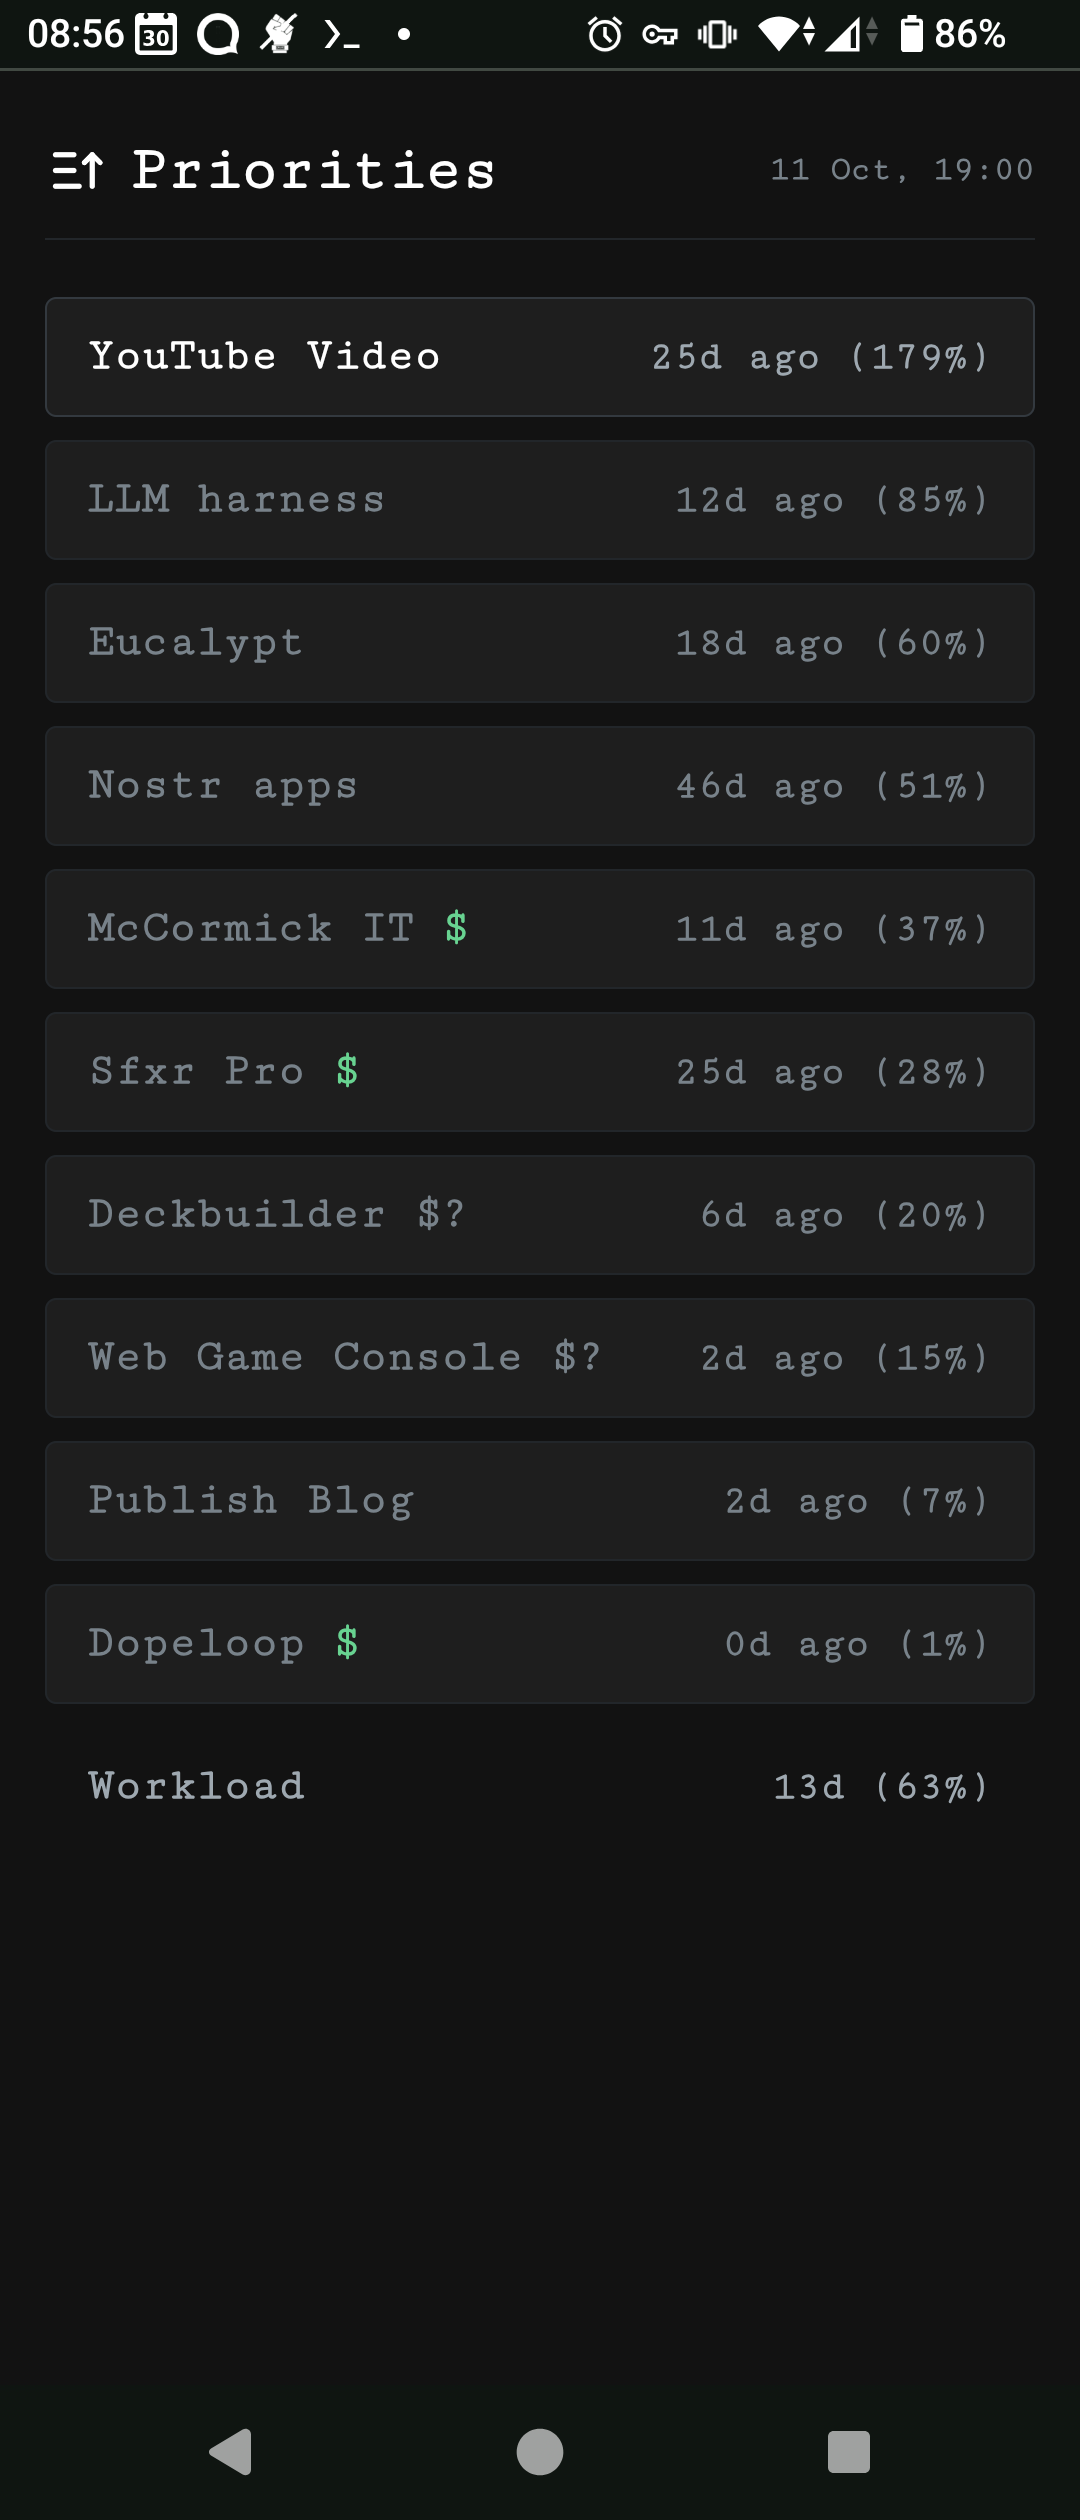
> Projects priority list which tells me what to do each day based on last update for each project (each project has a desired frequency of work and it prioritises by "lateness"). Checks git activity and RSS feeds to see what I'm neglecting
I've been meaning to find or build something like this for a while, specifically for house maintenance and projects. Did you make this yourself? Available anywhere?
The projects are stored in a YAML file with entries for name, source, and desired frequency.
Then the script just ranks them by how overdue they are relative to the desired frequency.
The source field can point to an RSS feed (for YouTube and blog), a git working folder, or any other type of folder. It basically checks if there's anything new depending on the source type and that's how it knows something has been worked on.
For house maintenance tasks you could simply tap to mark something as "I did this today" and have it save to localStorage or whatever.
Good inspiration, thanks. I intend to add a few more things like a section for notes/pictures and ranking by importance, but this looks like a good starting point


> People younger than 60 who drank one to four cups of coffee, particularly filtered coffee, had lower rates of artery disease and death
> The study is observational and doesn't prove that filtered coffee is healthier than unfiltered coffee
> a cup of unfiltered coffee contains 30 times more diterpenes than a cup of filtered coffee
This sentence in particular is kinda meaningless without specifying the specific amounts and what they mean. For instance, saying "an unfiltered cup of coffee contains 30 times more salt than a filtered cup" would not mean much if one contains 1 ug and the other 30ug, but would be very significant if it was e.g. 1 vs 30g
reply