I have an idea about it via multi-tier AI-generated templatized math problems with AI-generated solution verifier functions. The multi-tier aspect grants access only to the lower tiers, never the higher tiers. Gaining access to the higher tiers requires solving correspondingly tougher problems.
A provider can genuinely avoid storing inputs, as the Baseten engineer below describes. That is still different from proving what code received the prompt or protecting plaintext while it runs; I built TrustedRouter to separate ZDR, attestation, and confidential routes: https://trustedrouter.com/blog/attestation-is-all-you-need?u...
> to separate ZDR, attestation, and confidential routes
Could you please clarify what that means? Given what I've been searching for, I might in principle be part of your intended customer profile, but I can't figure out whether you are merely doing routing (alternative to OpenRouter) or also inference (alternative to the names I've mentioned above). If it's merely routing, then how do you protect me from any potential misbehavior on the part of the inference provider?
Just feedback for what you're building, so please take this in a positive spirit... I'm an AI researcher and not quite an infra guy, and I'm making recommendations on token APIs for several less knowledgeable around me (I've gotten a few people set up with Baseten recently), and I couldn't figure out whether/why I would be interested in TrustedRouter. You should communicate the story better :-)
EDIT: Here's what I now understand after some digging; please correct if wrong.
There are some M token providers (not the names I listed above?) who provide cryptographic guarantees about inference services. But somebody still needs to verify what they do on each request. For an individual running a single harness, that harness would be a logical place to perform this verification if possible. For an org with N users each running their own harness, TrustedRouter solves the N*M problem and becomes the single gateway for trusted inference -- provided one somehow trusts/verifies TrustedRouter.
hm- does the model that wrote this know that labs already pay for training data- that stuff scraped from the Internet is not particularly where today's capability gains come from?
They’ve settled some lawsuits and have a few licensing deals, IMHO they are not free from the accusations of pirating.
And look, I’ve pirated material in a past life, I was all about information wants to be free, but I’ve learned something about consent since then and try not to ignore the contract that creators offer when they publish something: you buy my book, and do whatever you want with it on the second hand market. Buy my book second hand that’s fine. But don’t go downloading every book that’s ever been scanned to create a service that destroys writers’ ability to make a living and act like you’re doing us all a favor.
Where are you getting your information from? From all I've seen the RL gives an incremental improvement, most of the capability increase comes from new model architectures (eg the jump from opus to fable is greater than the jump from opus 4.5 to 4.8)
they pay for some data but they take all of the stuff you’re throwing in too; that’s why i propose forcing it since they’re already used to paying for data just increase the cost even further
NEAR AI does a lot of things right but with this kind of thing, it only takes one mistake to completely break security.
If you look at [0] (the code they run in the CVM), there are a couple of things that worry me:
- They ship logs out of the CVM and worse, they send them to third parties (DataDog). Even if we could verify every bit of code running in the TEE, it's not enough to know the code doesn't maliciously ship prompts to a third party, we also need to audit what each binary logs.
- SGLang, the core inference engine, isn't reproducibly built. We have no way to verify that the thing they call "SGLang" is what they claim it is.
Really, it's the log shipping processes that worry me the most. Ideally, NEAR would minimise how much auditing needs to be done by having the minimal open-source proxy be the only thing with network access, making it much easier to audit potential exfiltration routes.
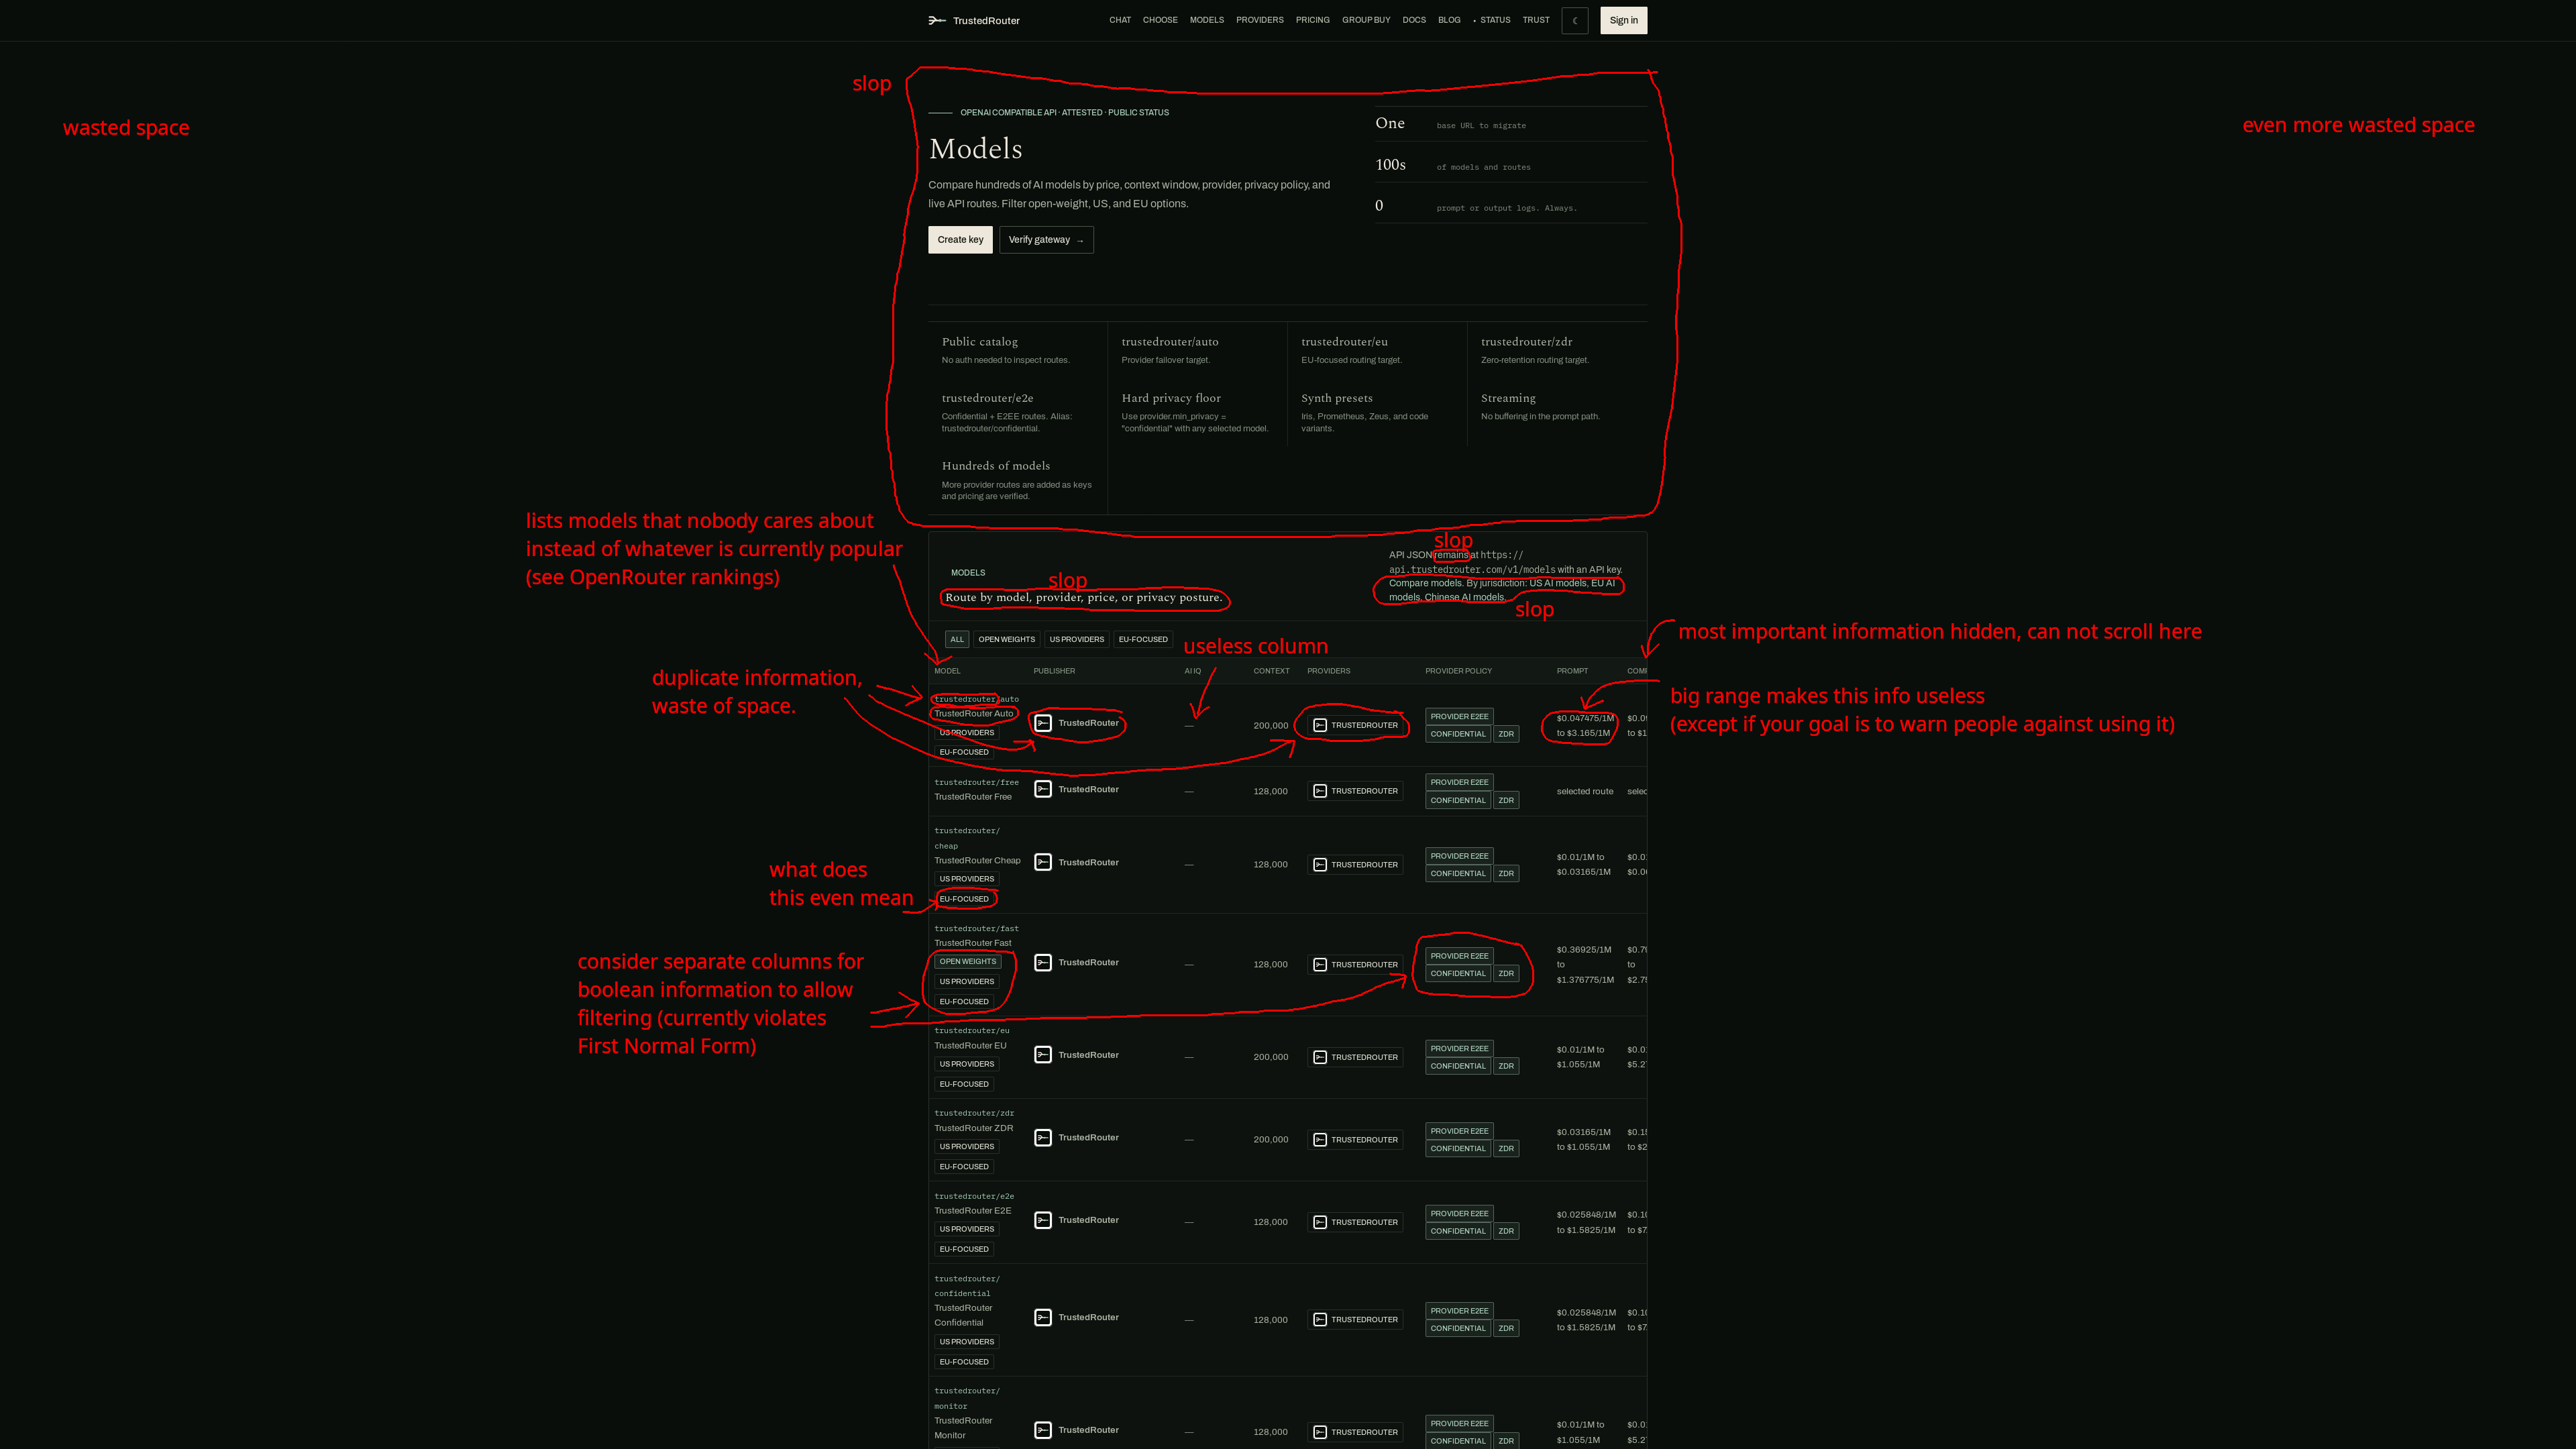
I have seen you advertise your website a few times. I like the idea of not having to trust the router, so I took some time out of my day to critique your website: https://files.catbox.moe/v68cf7.png
My visit to your website went like this:
1. Visit models page
2. Try to find GLM-5.3-Flash (which is among the ~5 models that 90% of people currently care about)
3. Give up scrolling (which would have taken OVER 50 SCROLLS!!!) and use Ctrl + F
4. Try to find input/output/cached price
5. Scroll all the way up to find out which column is what
6. Notice that output price is cut off
7. Notice that the scroll bar is over 100 scrolls further down the page
8. Use Shift + Wheel to scroll horizontally (most visitors probably won't know this trick)
9. Notice that cached price is missing
10. Conclude that this is probably not a serious offering and bounce
There are probably more issues later on, but this is how far I got.
I would suggest you to:
- Deslopify all pages that a user may visit before conversion
- List important models first (see OpenRouter rankings)
- Move the most important information (model name/input/output/cached price) to the left
- Disaggregate the prices per provider (maybe subtables per model? not sure)
- Measure cache hit rate and compute effective price per provider (see OpenRouter)
(- Optional: Fix the broken link on your HN profile page. Currently, the only way to get from this comment to your website is a search engine.)
How am I supposed to navigate around there? For example the pricing page is empty or is that how it was supposed to look? On models and providers pages there are lists but no way to filter or get any kind of meaningful info. Or is this a WIP/POC?
The serving endpoint can censor. At TrustedRouter we ran the same GLM-4.7 weights on both hosts: Cerebras answered all 60 FreedomBench questions; one Z.ai endpoint went blank on 27.


mev (based on mercury) gemmev (based on gemma)
also these take images input
zev, lev etc
https://trustedrouter.com/docs/decide
reply